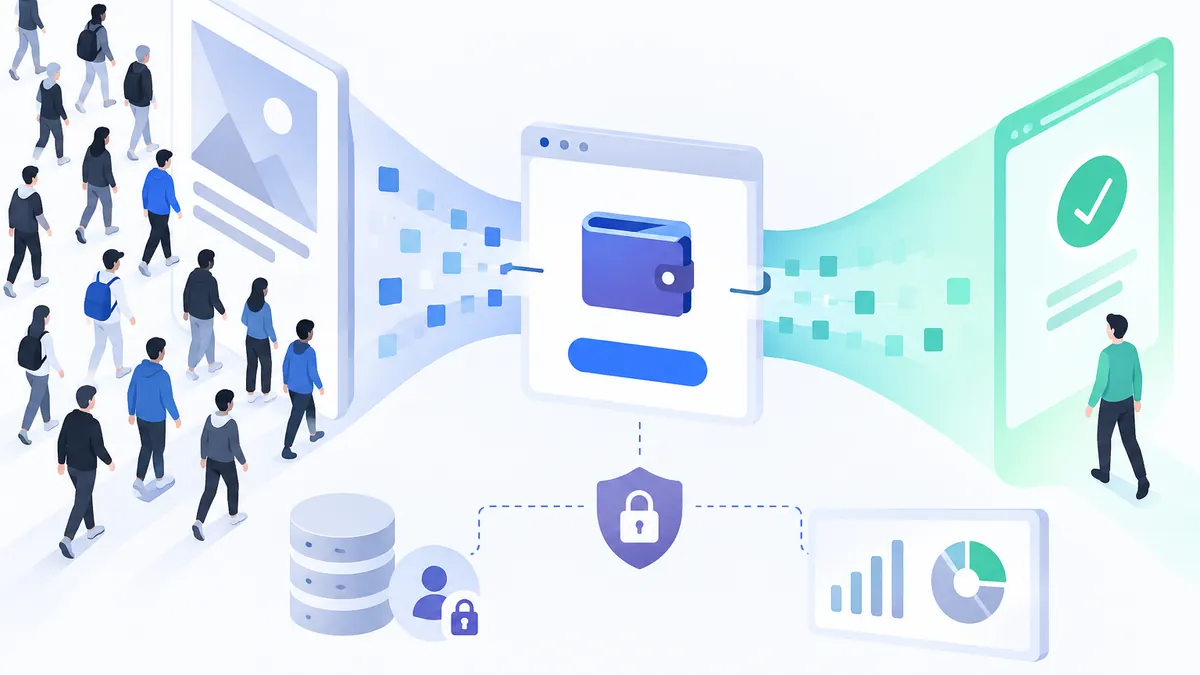
A campaign that produces thousands of wallet connections can still fail to bring people into a product. Some visitors connect out of curiosity, some encounter a transaction error, and others create multiple addresses. A connection is a useful step in onboarding, but it is not the same thing as successful use.
A better growth experiment follows the journey from campaign exposure to a clearly defined product action. The goal is not to identify every person behind an address. It is to gather enough reliable evidence to decide which message, audience or onboarding path deserves another test.
Define activation and assemble the campaign evidence
Activation is the first observable action that represents a meaningful step toward the product’s intended value. For a wallet-enabled payments application, that might be a completed test payment. For a governance interface, it might be submitting a first vote. Choose an action that is relevant to the product and technically measurable; opening the wallet selector alone rarely meets that standard.
Once the definition is set, a marketing workspace such as OhlasAi is an optional way to review prepared campaign exports, spreadsheets and creative briefs for performance issues and possible tests. The team still needs to collect and prepare its own measurements; the homepage does not establish native blockchain analytics or wallet attribution.
Write the activation rule before launching. Specify the event, the eligible audience, the time window and whether a test-network action qualifies. For example: “A visitor activates if they connect a wallet and complete a test payment within seven days of their first tagged visit.” Also state which network and application environment count, and how failed or reversed actions are treated.
Assemble the evidence in separate layers: campaign spend and clicks from the advertising platform; visits and onboarding events from the application; and, where relevant, transaction status from the application’s own monitoring or a blockchain data source. Record the date range, time zone and export time for each source. These records may use different counting rules, so a click total should not be expected to match a visit total exactly.
Decide what the denominator represents. “Activated sessions divided by eligible sessions” answers a different question from “activated wallets divided by connected wallets.” If the system cannot reliably recognise a returning person, label results as sessions, browser identifiers or wallet addresses rather than unique users. Each can be useful, but none automatically proves person-level reach.
Instrument the journey from campaign visit to meaningful product use
Map the minimum funnel before adding more dashboards: tagged landing-page visit, wallet-connect attempt, successful connection, initiation of the product action and completion. Capture failures separately where practical. A completed transaction may require confirmation after submission, so distinguish “submitted” from “confirmed” and define the confirmation threshold used for the experiment.
Use consistent campaign parameters across variants. Google’s guide to Traffic-source dimensions, manual tagging, and auto-tagging explains how tagging populates dimensions such as source, medium, campaign and ad content. A shared naming convention lets a team compare exports without later guessing whether two labels refer to the same placement. Tagged visits classify traffic; they do not establish a unique person or provide complete cross-device attribution.
Test instrumentation before buying traffic. Run a small internal journey through each variant and check that events arrive in the expected order, identifiers have the intended scope and timestamps use a consistent time zone. Check both successful and failed connections. If an event is missing for one browser or wallet type, an apparent campaign difference may actually be a measurement defect.
Privacy is part of instrumentation, not a cleanup task. The privacy roadmap for Ethereum explains that public transaction data exposes transfers and that infrastructure providers can observe IP addresses, queried wallet addresses and activity patterns. As a practical precaution, avoid unnecessary joins between identifiable marketing records and wallet addresses. Do not place email addresses, wallet addresses or other sensitive identifiers in campaign URLs. Limit access, retention and exports to what the experiment needs, and assess applicable consent and legal requirements.
Attribution will remain incomplete. A visitor may see an ad on one device and connect on another, block analytics or return through an untagged route. A wallet may also be shared, replaced or used across several browsers. Report the share of events that can be linked within the chosen measurement method, and retain an “unknown source” category instead of forcing every action into a campaign.
Design a test that separates acquisition quality from wallet noise
Start with one decision and one change. If the question is whether a security-focused message brings better-qualified visitors than a convenience-focused message, keep the destination, offer and onboarding flow as similar as possible. Assign eligible traffic randomly to the two versions where the tools allow it, and avoid changing budgets, targeting or landing-page behaviour midway through the test without recording the change.
Define the primary metric and stopping rule in advance. For example, compare the proportion of eligible, measured landing sessions that reach activation within seven days. Record the cost per measured activation as a secondary metric, alongside connection and completion rates. Estimate the sample size needed for a useful comparison before launch; if the available audience is too small, treat the exercise as exploratory rather than expecting a conclusive winner.
Worked example: A team tests two landing-page messages for a wallet-based payment demo. Version A receives 1,000 eligible measured sessions, 300 successful wallet connections and 60 completed test payments within seven days. Version B receives 1,000 eligible measured sessions, 220 connections and 70 completed payments. A has the higher connection rate, 30% versus 22%, but B has the higher measured session-to-activation rate, 7% versus 6%. Its connection-to-activation rate is also higher, about 32% versus 20%.
Those figures do not prove that B is better. The difference in activation is small, and a proper uncertainty analysis may show that the data are compatible with several outcomes. Costs may also differ: if A and B each cost €500, their observed costs per measured activation are approximately €8.33 and €7.14 respectively, before accounting for missing attribution or other costs. These are illustrative figures, not a forecast. Complete the seven-day observation window for both groups before comparing them.
Wallet counts introduce additional noise. One person can use multiple addresses, while a single address can represent a shared or automated setup. Deduplicating exact repeated addresses can prevent counting the same address twice under a stated rule, but it cannot reveal the number of people behind those addresses. Bots, incentive hunters and internal testers can also inflate results. Document any exclusion rule in advance, retain an unfiltered aggregate for comparison, and explain how sensitive the result is to those exclusions.
Random assignment helps reduce systematic differences between groups; it does not repair broken tracking or prevent outside changes from affecting the test. If randomisation is unavailable and two campaigns target different audiences or run at different times, describe the comparison as observational. A higher activation rate may reflect audience mix, timing or placement rather than the message itself.
Use AI to propose explanations, then verify them
Once the exports are cleaned and aggregated, an AI assistant can help organise a review: summarise the funnel, flag unusual differences between segments or suggest questions for a creative test. Supply a data dictionary with each column, unit, date range and known limitation. Ask for hypotheses and the evidence that would distinguish them, rather than asking the system to declare why a campaign succeeded.
For the example above, an assistant might suggest that version B attracted visitors with stronger intent, or that version A’s promise did not match the payment demo. Both are plausible explanations, not established facts. Before acting, check the actual ad copy and audience settings, verify event definitions and compare breakdowns by device, wallet type and placement where sample sizes permit. A broken connection flow in one segment could produce a similar pattern.
The operating principle described at https://www.ohlas.uk/about is a useful model for oversight: users review and adjust AI recommendations and make the final decision. That principle does not validate any particular recommendation. A reviewer still needs to trace claims back to the underlying export, confirm calculations independently and identify what the data cannot show.
For a practical verification pass, ask three questions: Did the proposed explanation use the right denominator? Could missing or delayed events account for the pattern? What small follow-up test would challenge the explanation? Keep a record of rejected suggestions as well as adopted ones, and avoid uploading raw identifiers or confidential records unless there is a justified need and appropriate permission.
Decide whether to stop, revise or repeat the experiment
At the end of the observation window, compare the primary metric with its uncertainty, then inspect cost, funnel drop-off and data quality. If tracking failed for a substantial or uneven share of traffic, repair it and rerun the test rather than treating incomplete data as a marketing insight. If both variants attracted connections but few completed the product action, investigate onboarding friction before increasing acquisition spend.
Choose a next step that matches the evidence. Stop a variant when it is clearly unsuitable for the product or exceeds a predetermined cost limit. Revise it when the results identify a specific, testable problem, such as a mismatch between the ad promise and the landing page. Repeat or extend the experiment when the difference matters commercially but the available data are too uncertain to support a decision. Do not keep checking results and selectively stop at the first favourable fluctuation.
Finally, preserve a short experiment log: hypothesis, assignment method, audience, dates, creative, activation definition, exclusions, spend, results and caveats. This makes later comparisons more useful and prevents a wallet connection from becoming an inflated claim about users. The objective is not a perfect count of every person; it is a defensible decision about how to improve the next version of the product and its acquisition path.